Current question
Does measuring help a model lay out a Venn? With a bit more statistics.
So far
Sol kept the labels clear nine times out of ten whether I gave it a list, told it to check itself or said nothing. Read the post
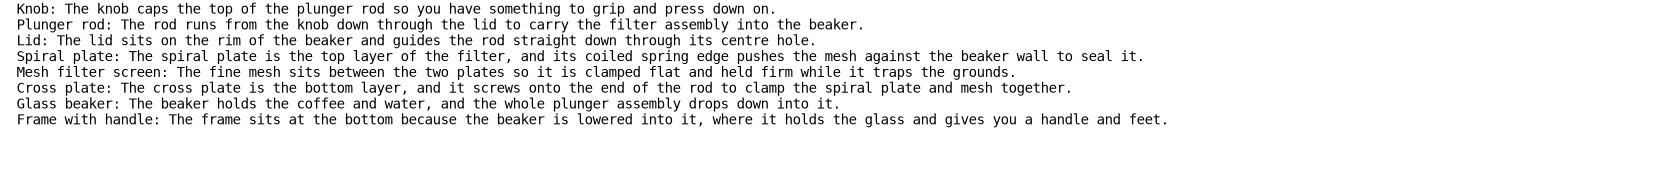
Opus 5.5 knows the order of filter in a french press, but can it draw it?
Asked in words, Opus 5.5 got the filter order right in 5 of 5 runs, and asked to draw it, in 2 of 5.
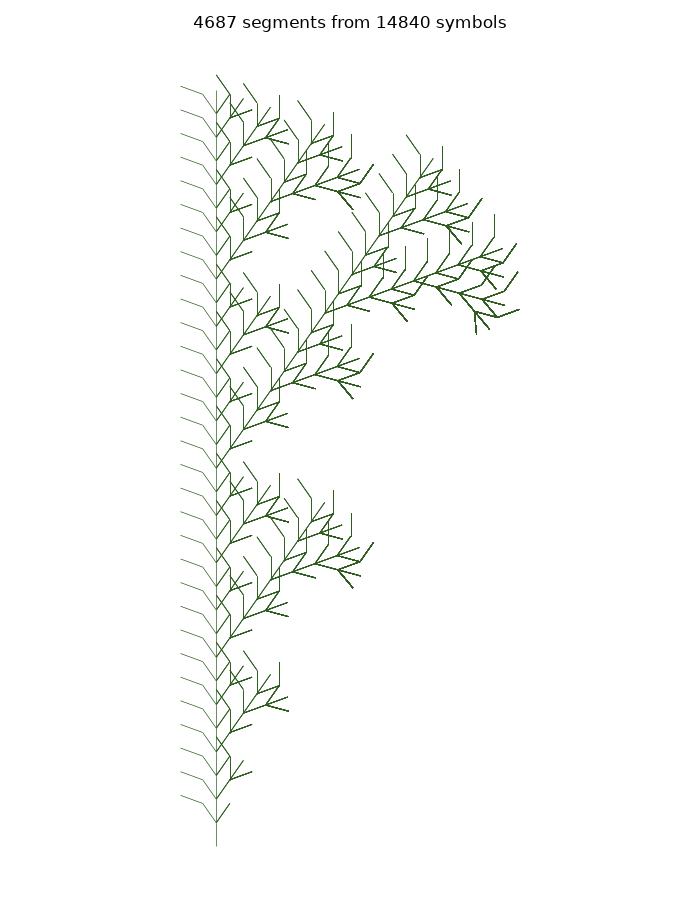
L‑systems are fun ways to get very varied output
Models drawing a half pruned coffee tree
Sonnet 5.5 against Opus 5.5, which one costs more and perform bests on the Venn, the French press and the shrub?
Opus wins the Venn, Sonnet wins the French press and the shrub, and Sonnet is twice as cheap on all three.
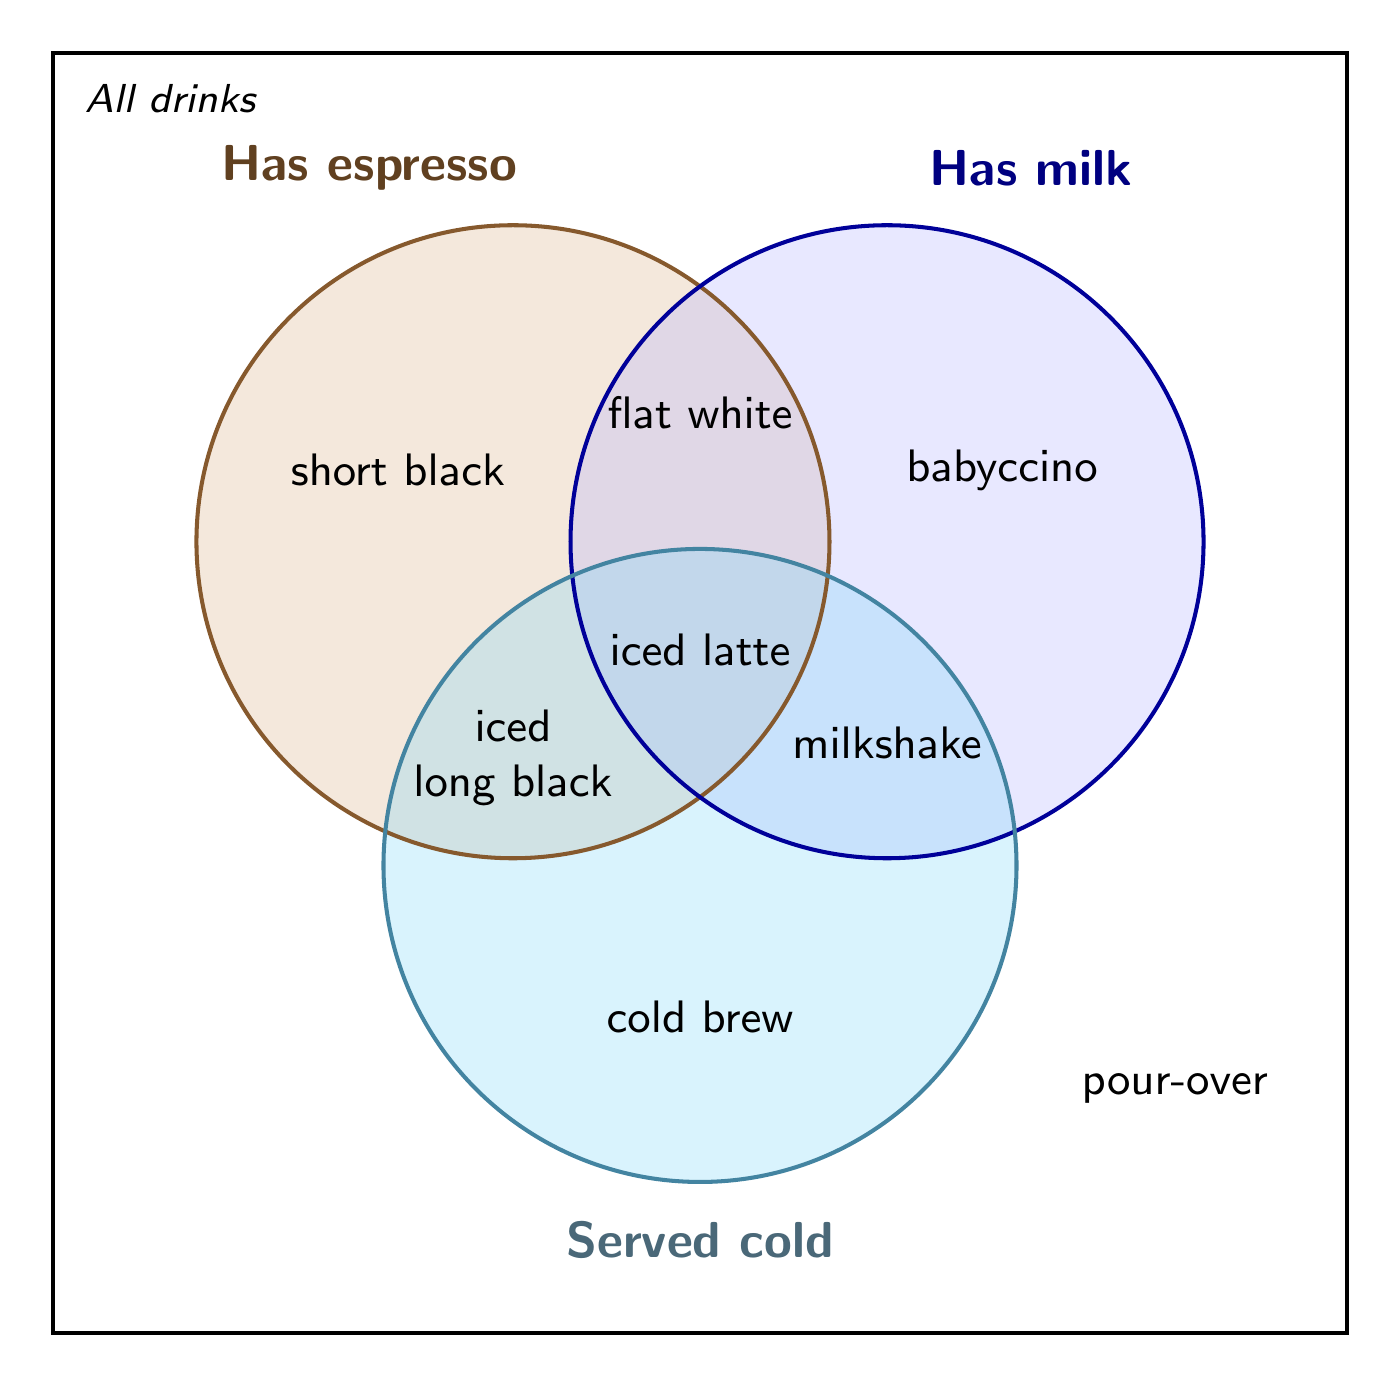
Does measuring help a model lay out a Venn?
Results seems to indicate that telling the models to keep labels off the lines worked as well as telling them to measure.
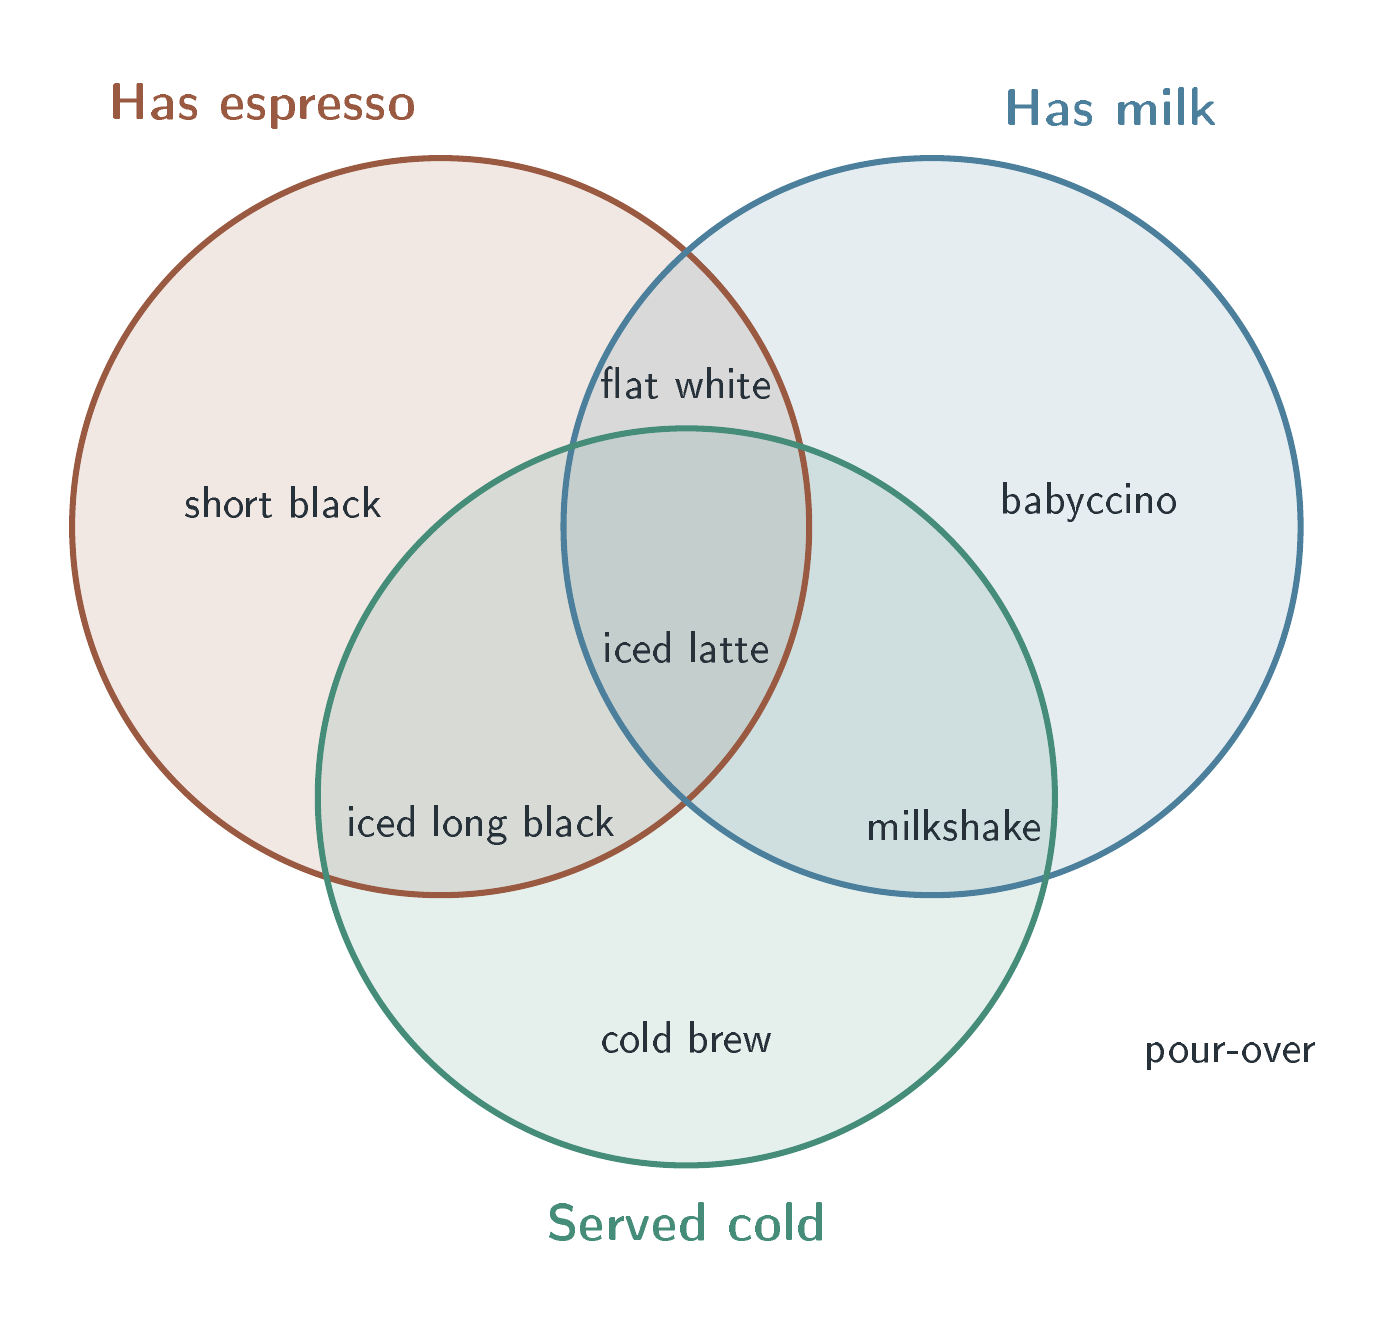
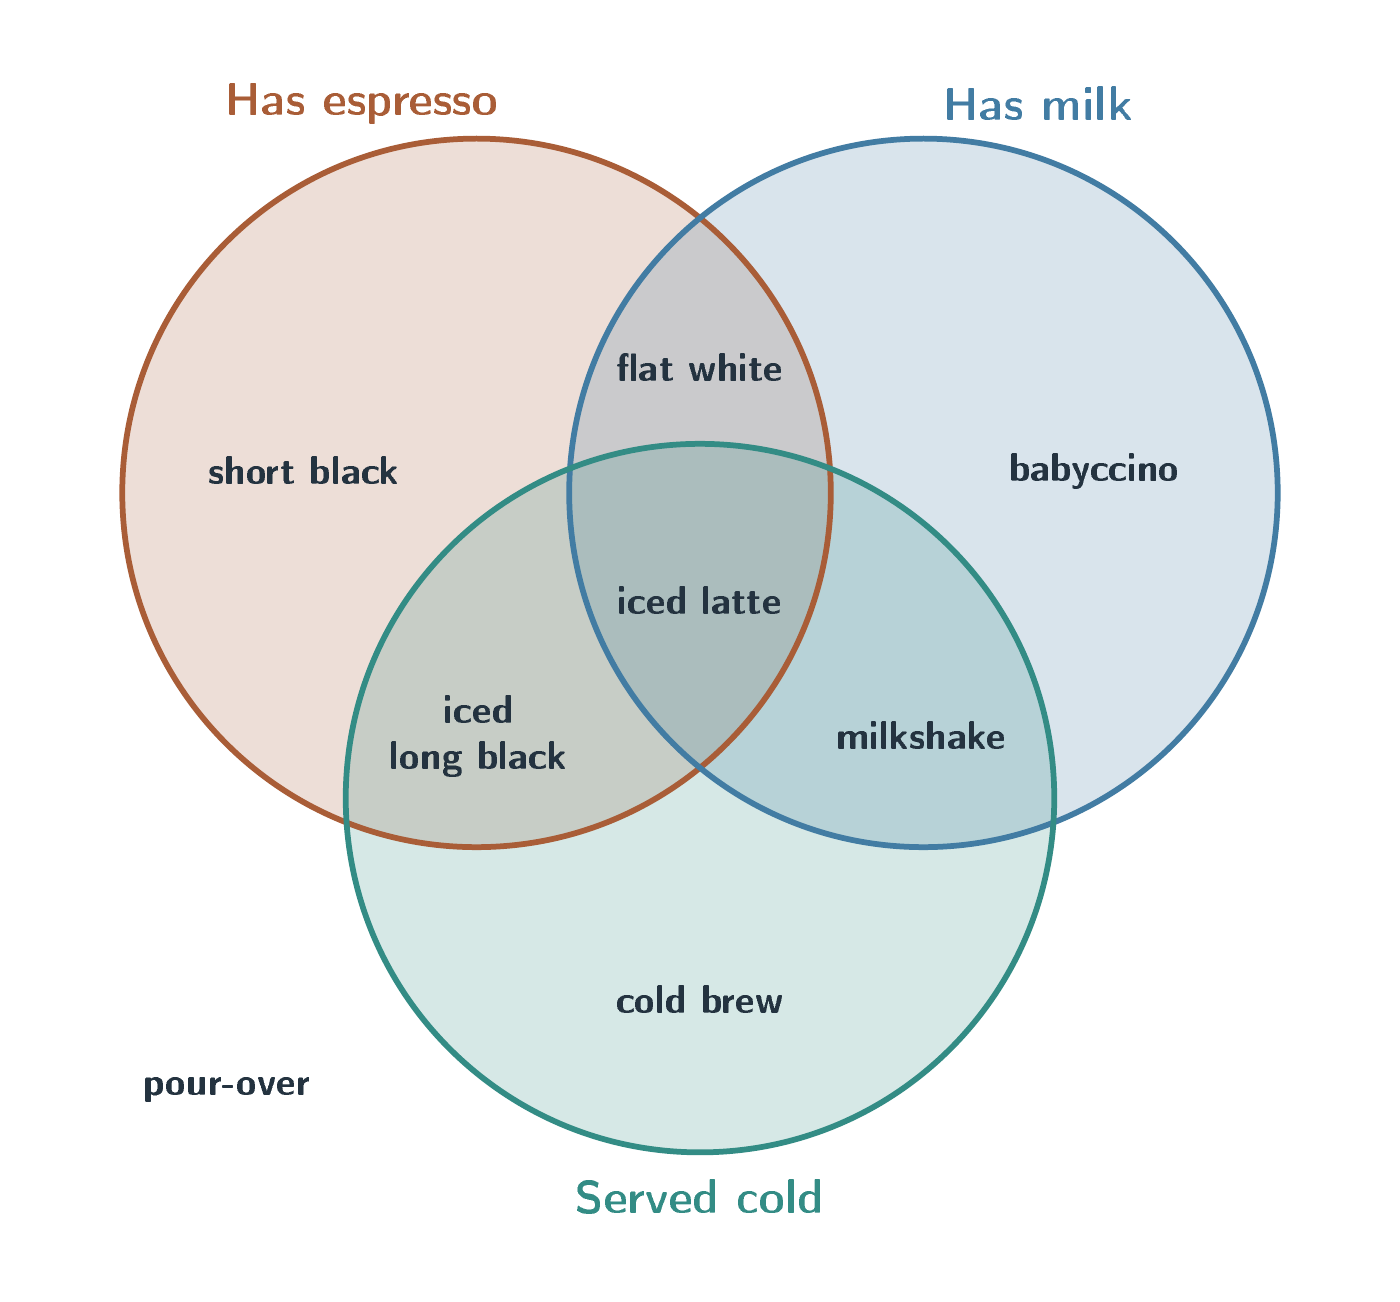
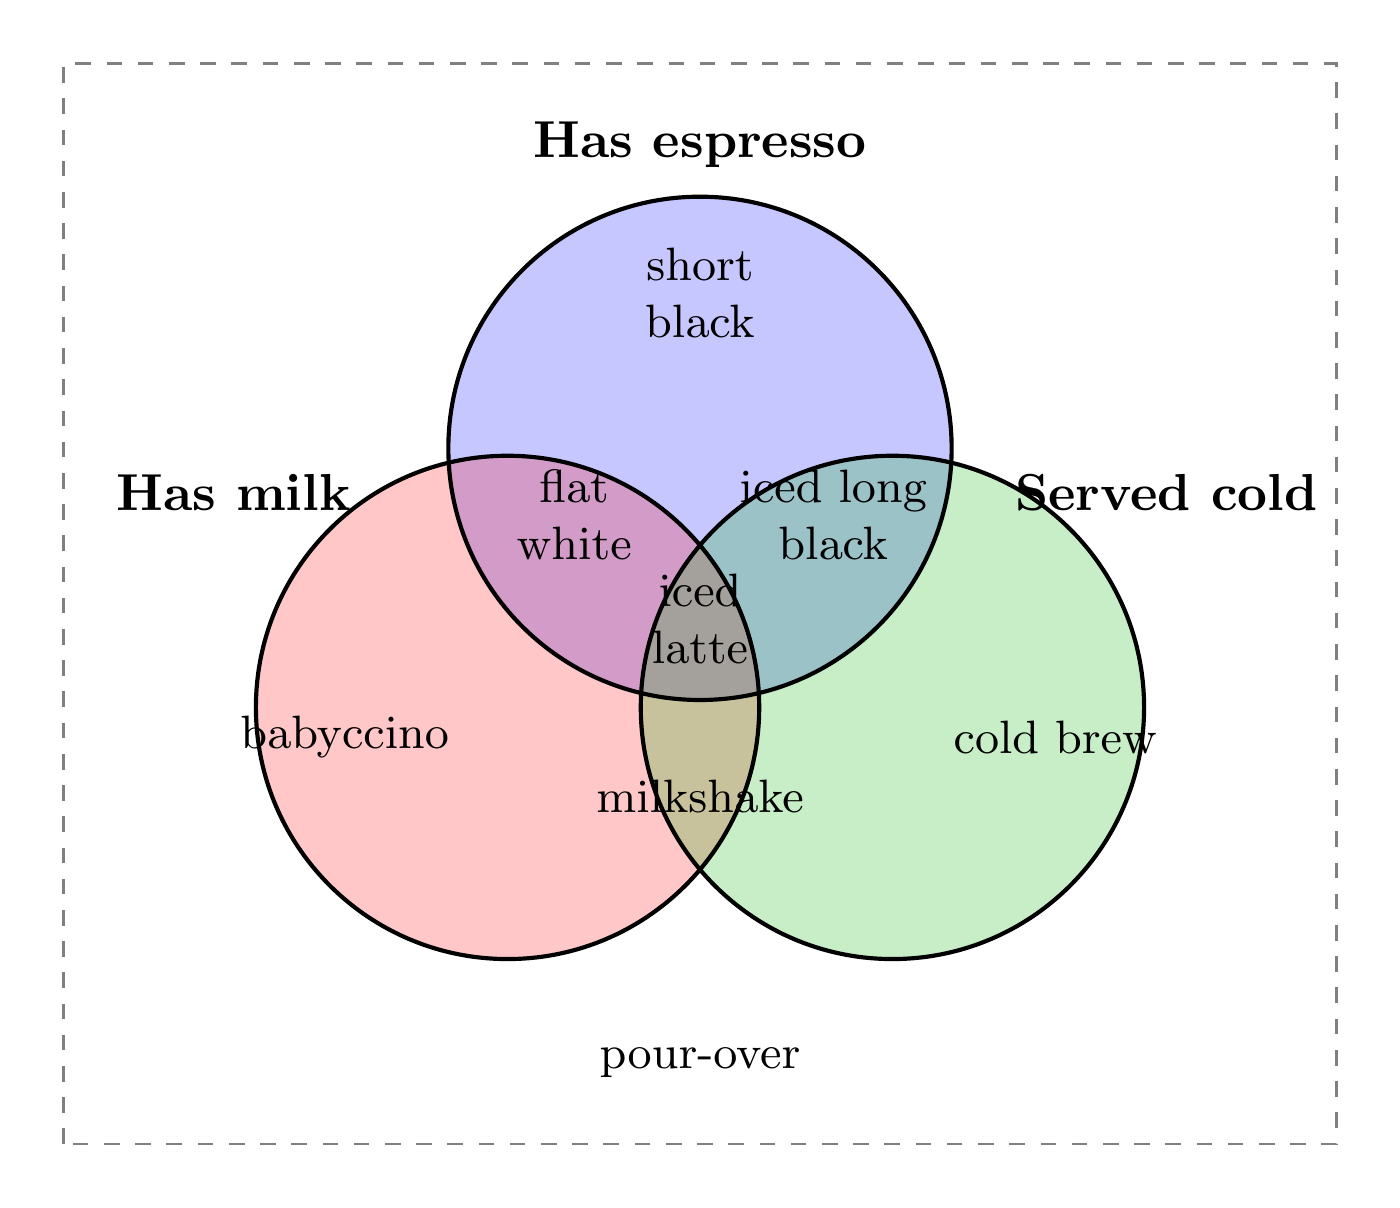
Qwen3.8 Flash vs DeepSeek 4.1 Flash draw a coffee Venn
Qwen gets all three runs right and DeepSeek only one.
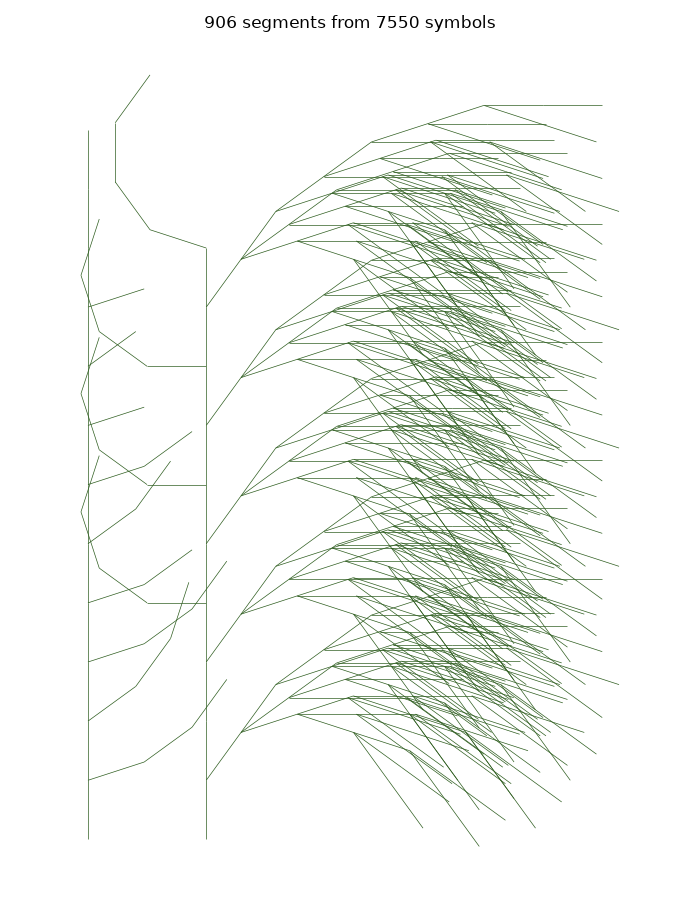
Qwen3.8 Max Prime draws three coffee shrubs
Three very different shrubs, and only one looks right.
Ten models draw a coffee Venn, some check with vision others with code
Almost all put the drinks in the right place, but only a few keep the labels off the lines.
Newest runs, three a model.
One square per check: passed, failed, undecided.
| Opus 5.5 | French press | |||
| Pareto | French press | |||
| Claude Sonnet 5.5 | French press | |||
| Claude Sonnet 5.5 | Venn | |||
| Opus 5.5 | Venn |
About
I give new AI models tasks with a right answer, on a theme that changes every few months, check what comes back against that answer, and wait for three runs before anything goes on the board. It is a notebook, so the prompts, the costs and my mistakes are all in the open.
If you are new, start with DeepSeek found the grader and ran it, Two of my headlines were wrong after three runs and Union Alpha spells COFFEE on the streets of Melbourne.